Decision horizon: how far ahead do you need to be right?
The first thing we ask is how far ahead you need to be right: tomorrow, next week, next quarter. That becomes the test the model must pass. We measure it at that distance against the simplest possible guess, “nothing will change”, and write the result down, including where it loses.
In plain terms“Right about what, by when?” is the first question. The model is then graded on that.
At a glance
The horizon is declared
A business input.
The null is “nothing changes”
Not our previous release.
Three verdicts, kept apart
Passed, failed and not measured.
A gate that refuses
And records why.
A model that scores well and decides badly
Most model reporting has three defects.
The horizon is chosen after the fact
A model is scored at whatever distance flattered it. You deploy it and find it is useless at the distance you need.
The baseline is another model
Beating your own last version proves nothing. The real question is whether you beat assuming nothing changes.
Failure is absent from the report
A model record with no failure modes is a marketing document. You cannot take it to a validation committee.
We fix all three by making the horizon a declared input and the baseline a naive one.
Four properties of a model that is allowed to serve
The promotion gate
What happens before a model is allowed to serve.
| Order | Check | Refusal means |
|---|---|---|
| 1 | Corpus provenance | The data that trained this model is not attributable, or is too self-referential to certify |
| 2 | Divergence | The model’s output is degenerate, not merely inaccurate |
| 3 | Beats the null | The model does not beat persistence at the reported horizons |
| 4 | Declared horizon measured | The horizon you require was never measured |
A refusal can be overridden by a human. When it is, the override is logged with the actor and the reason. The default posture is to refuse; using a bad model is a decision someone has to own. If the horizon you declared was never measured, the gate warns rather than silently passing: absence of evidence is recorded as absence of evidence, never converted into a pass.
The promotion gate refuses in a fixed order
- 1 · Corpus provenanceIn: Refuses in this orderLeads to: 2 · Divergence
- 2 · DivergenceIn: Refuses in this orderLeads to: 3 · Beats persistence
- 3 · Beats persistenceIn: Refuses in this orderLeads to: 4 · Declared horizon measured
- 4 · Declared horizon measuredIn: Refuses in this orderLeads to: Serve
- Serve
What you get for every model
- Per-horizon error, beside the persistence baseline at the same horizon
- The furthest horizon at which the model still beats that baseline
- The verdict: passed, failed or not measured, kept distinct
- Corpus provenance: which source produced the training rows, how many are unattributed, and whether more than one source is involved
- Promotion history: who promoted it, when, and whether the gate refused first
- Drift and inventory context: how the serving model compares to its sibling revisions
This is what a validation committee asks for. It exists as a first-class surface, not a spreadsheet someone maintains by hand.
Model report card · illustrative
| Category | Model error | The simple guess: nothing changes | Result |
|---|---|---|---|
| 1 step | 22 | 48 | Passed |
| 5 steps | 41 | 62 | Passed |
| 20 steps | 83 | 70 | Failed |
| 50 steps | This horizon was never evaluated | This horizon was never evaluated | Not measured |
Why we publish the failures
“A vendor who shows you only their good horizons is asking you to trust their judgment about which horizons do not matter.”
- You can deploy this without a leap of faith. The gate is a control you can point at.
- You find out early when it is not right for you. A failure recorded on a small evaluation is cheaper than one discovered after an integration.
If the model does not beat persistence in your domain on your data, you hear it from us.
The model record, on screen
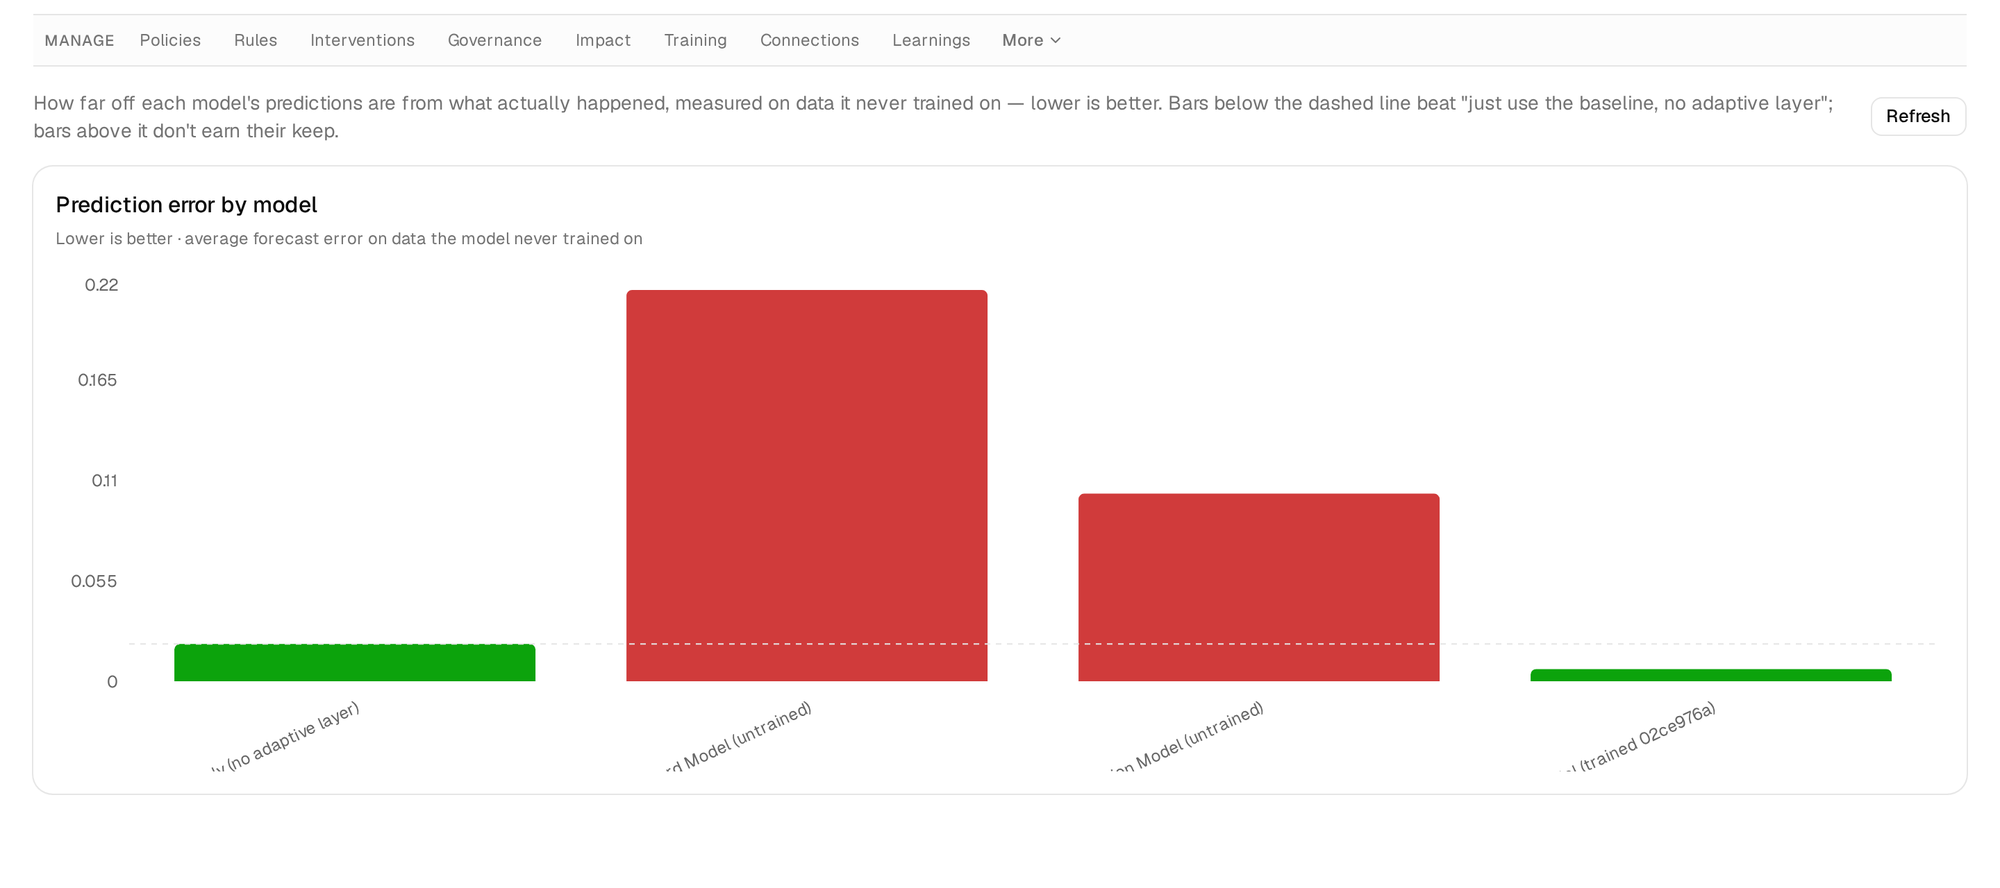
The reference-world model record includes a horizon where the model loses. That is deliberate.
Ask for the model record, including the losses
In a technical session we show the record for the reference world, then run an evaluation on a sample of your events.