Demo guide: 100 stores, 15 departments, one live company.
OgMart is a 100-store, 1–2 billion USD retailer running as a single live operation across merchandising, supply chain, distribution, inventory, stores, e-commerce, customers, pricing, payments, finance, treasury, workforce, facilities, IT and compliance.
A working session instead of a tour.
We stand up the reference world, then spend most of the time on your domain: what the entities are, what state moves, how far ahead you need to be right, and what the model record says when we evaluate against a naive baseline. Bring one domain, the one your team already argues about weekly.
The route through the world, in order
What to look at, and what to look for.
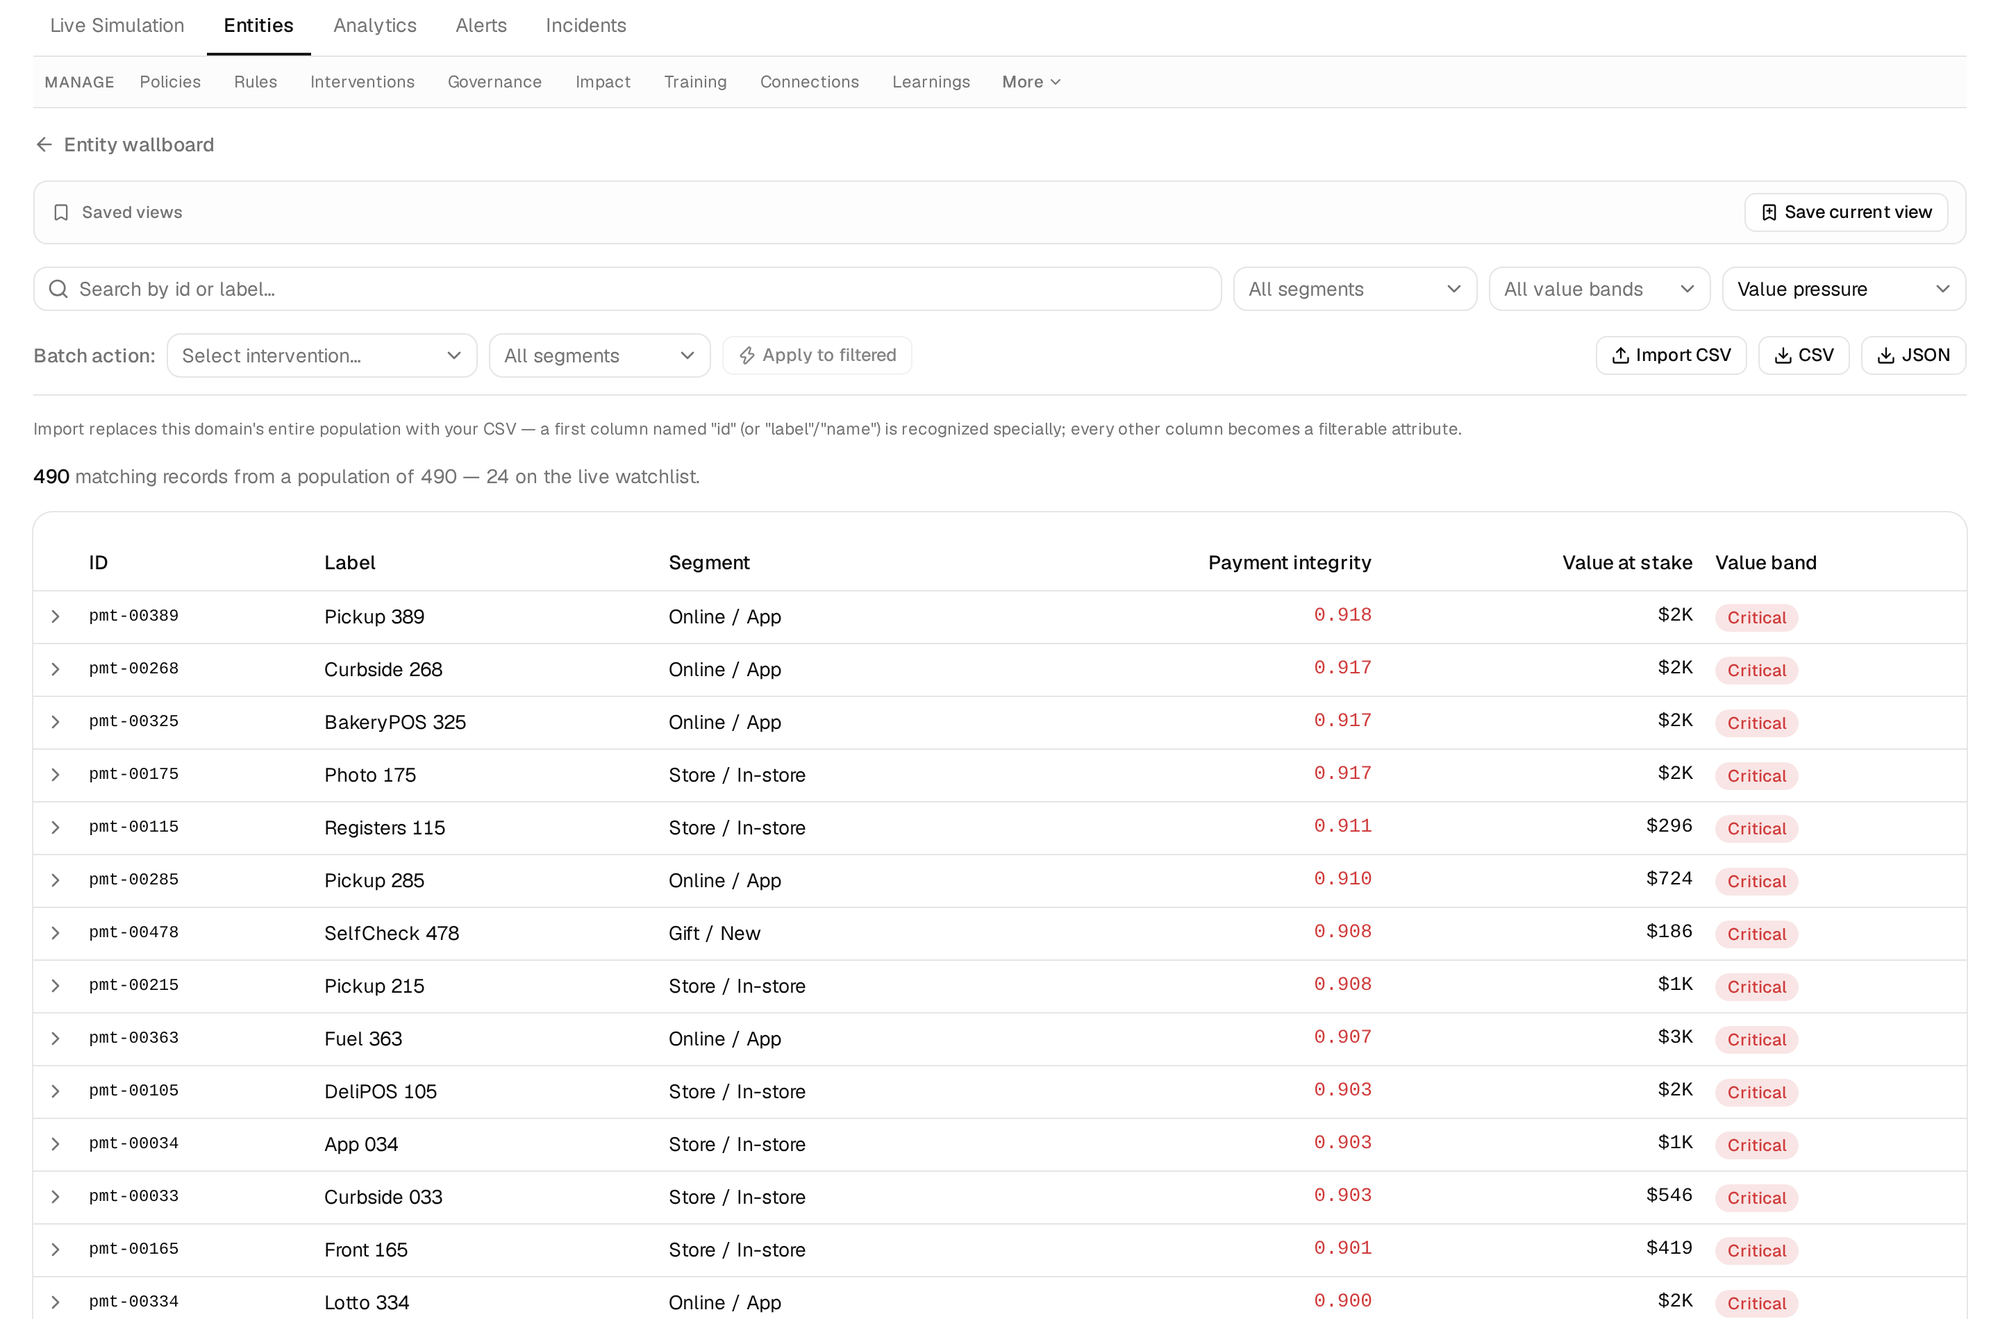
The queue · 30 seconds
Entities ranked by value at stake, with band, trend and time at risk. Look for: is the ordering defensible? Could you hand this to a team lead and have them work top-down?
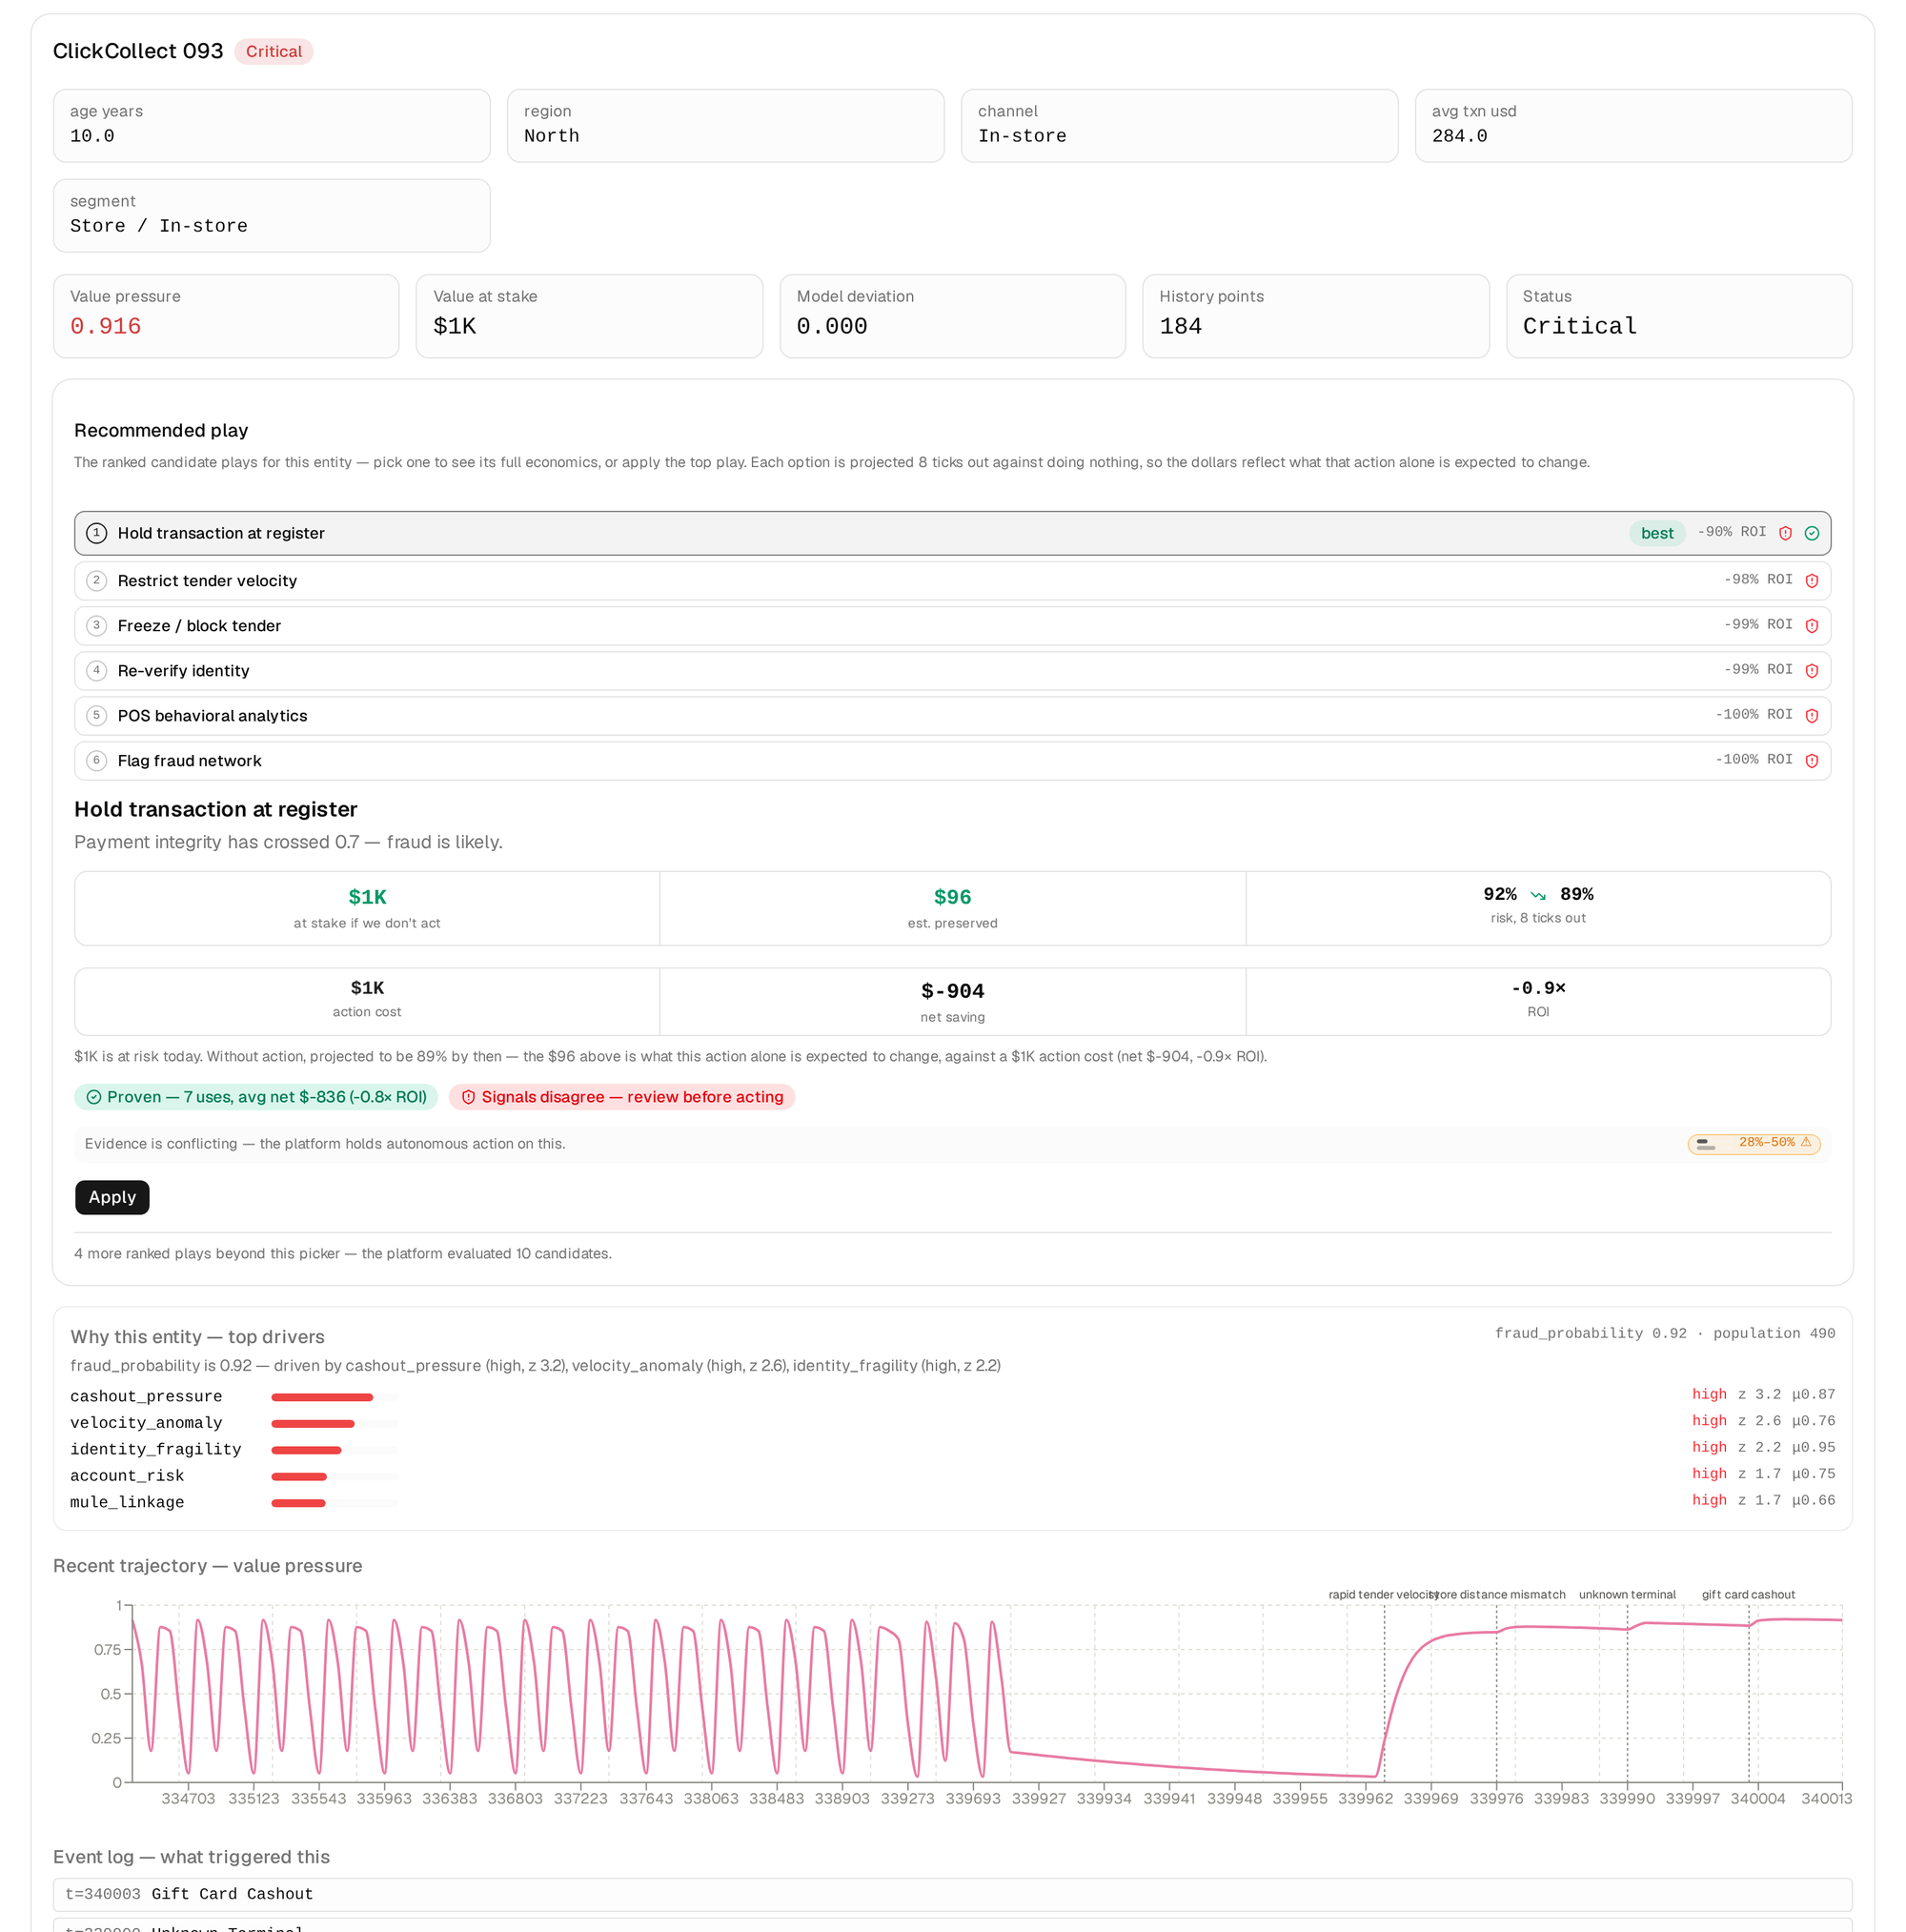
One entity, in depth · 2 minutes
A single entity’s state trajectory against the events acting on it, plus its evidence panel: belief, plausibility, uncertainty and conflict. Look for: does conflict ever go high, and does the platform treat that as interesting rather than smoothing it away?
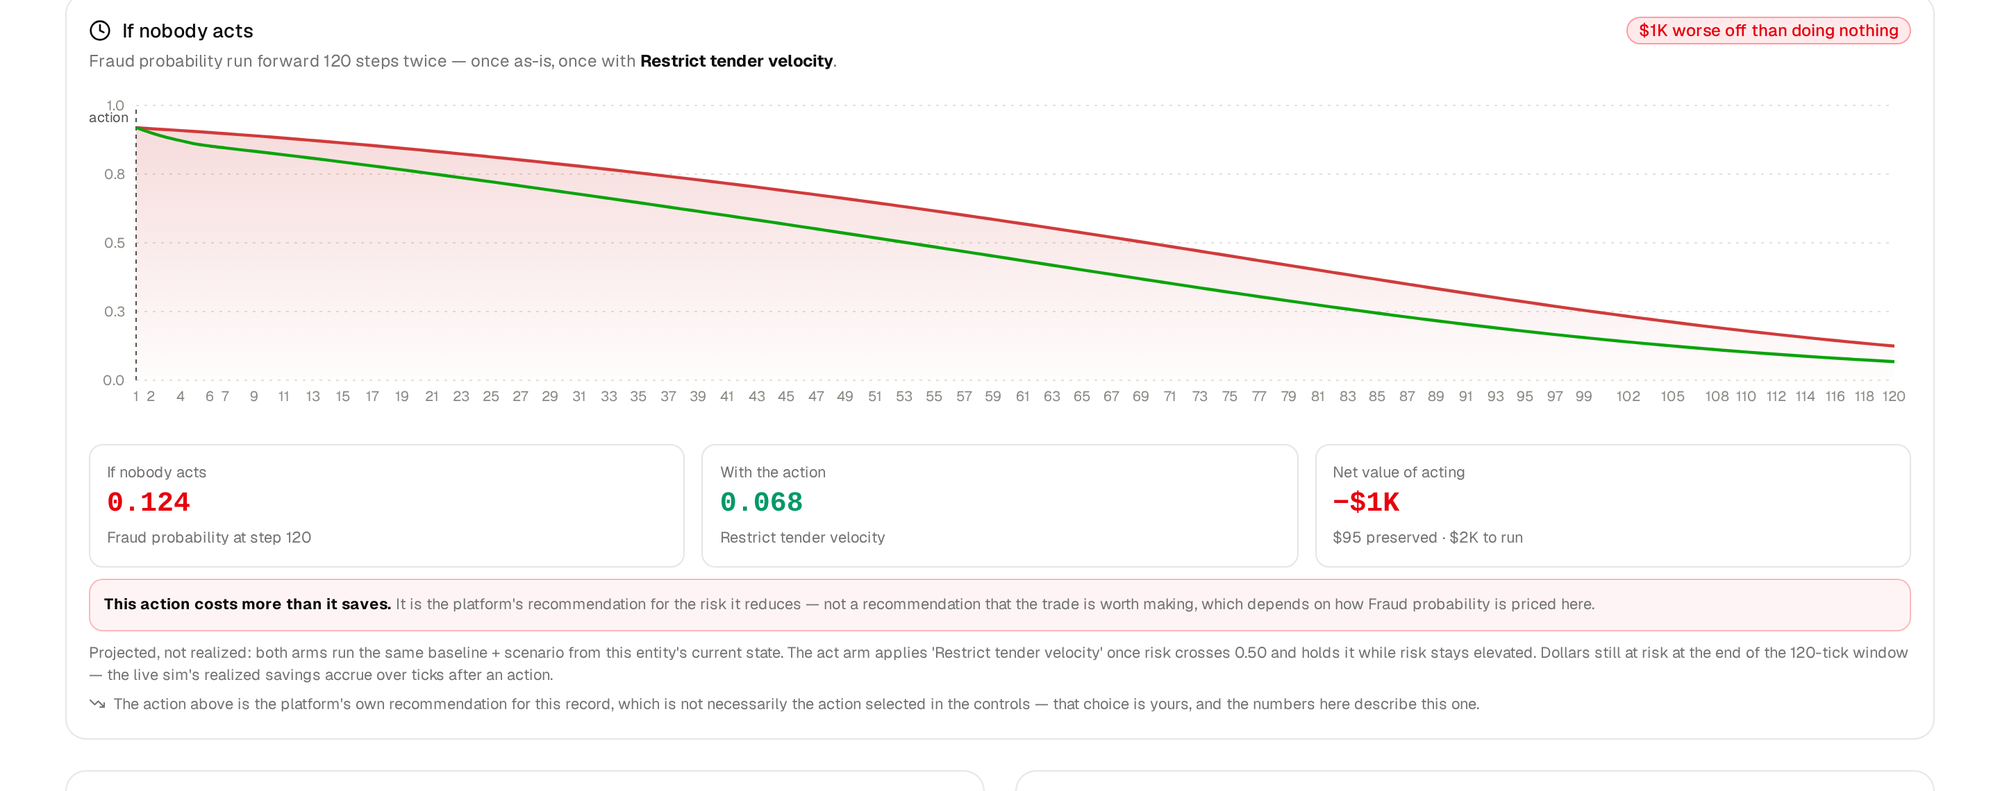
A priced decision · 2 minutes
An intervention with its cost, its modeled effect on the primary dimension, and the cost of waiting beside it. Look for: is the arithmetic inspectable? Can you see the assumptions? Does “do nothing” now have a price?
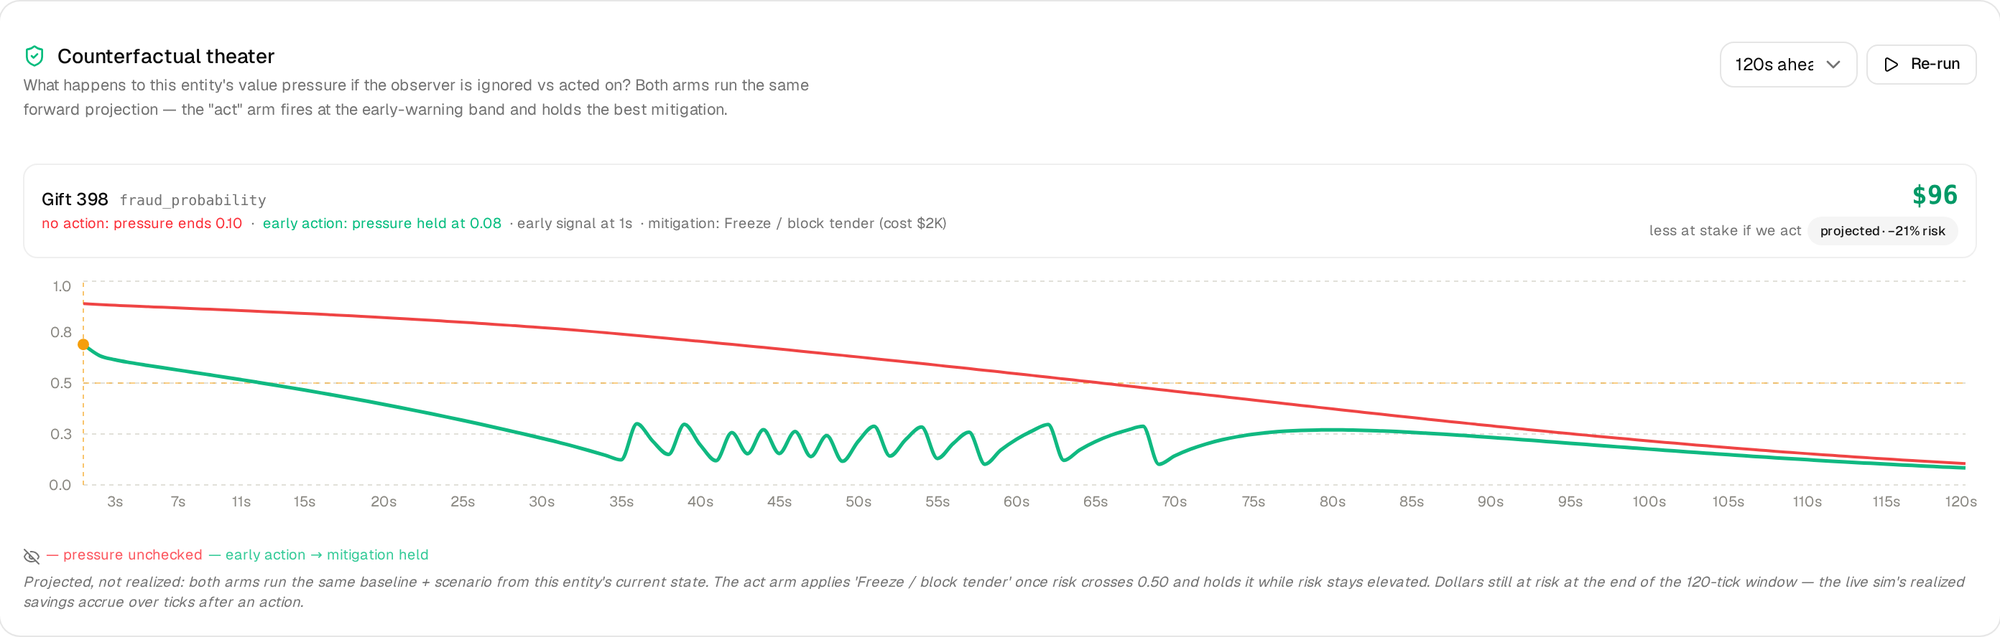
Counterfactual replay · 2 minutes
Run an entity’s real history again with an intervention applied at a chosen point. Two trajectories, side by side. Look for: does this replace a post-incident argument with a measurement?
The what-if, in your browser · 2 minutes
Fork the live state, change the lever, watch it recompute locally. Look for: no round trip, no spinner. Then ask the hard question: what if it is wrong here?
The model record · the one that matters
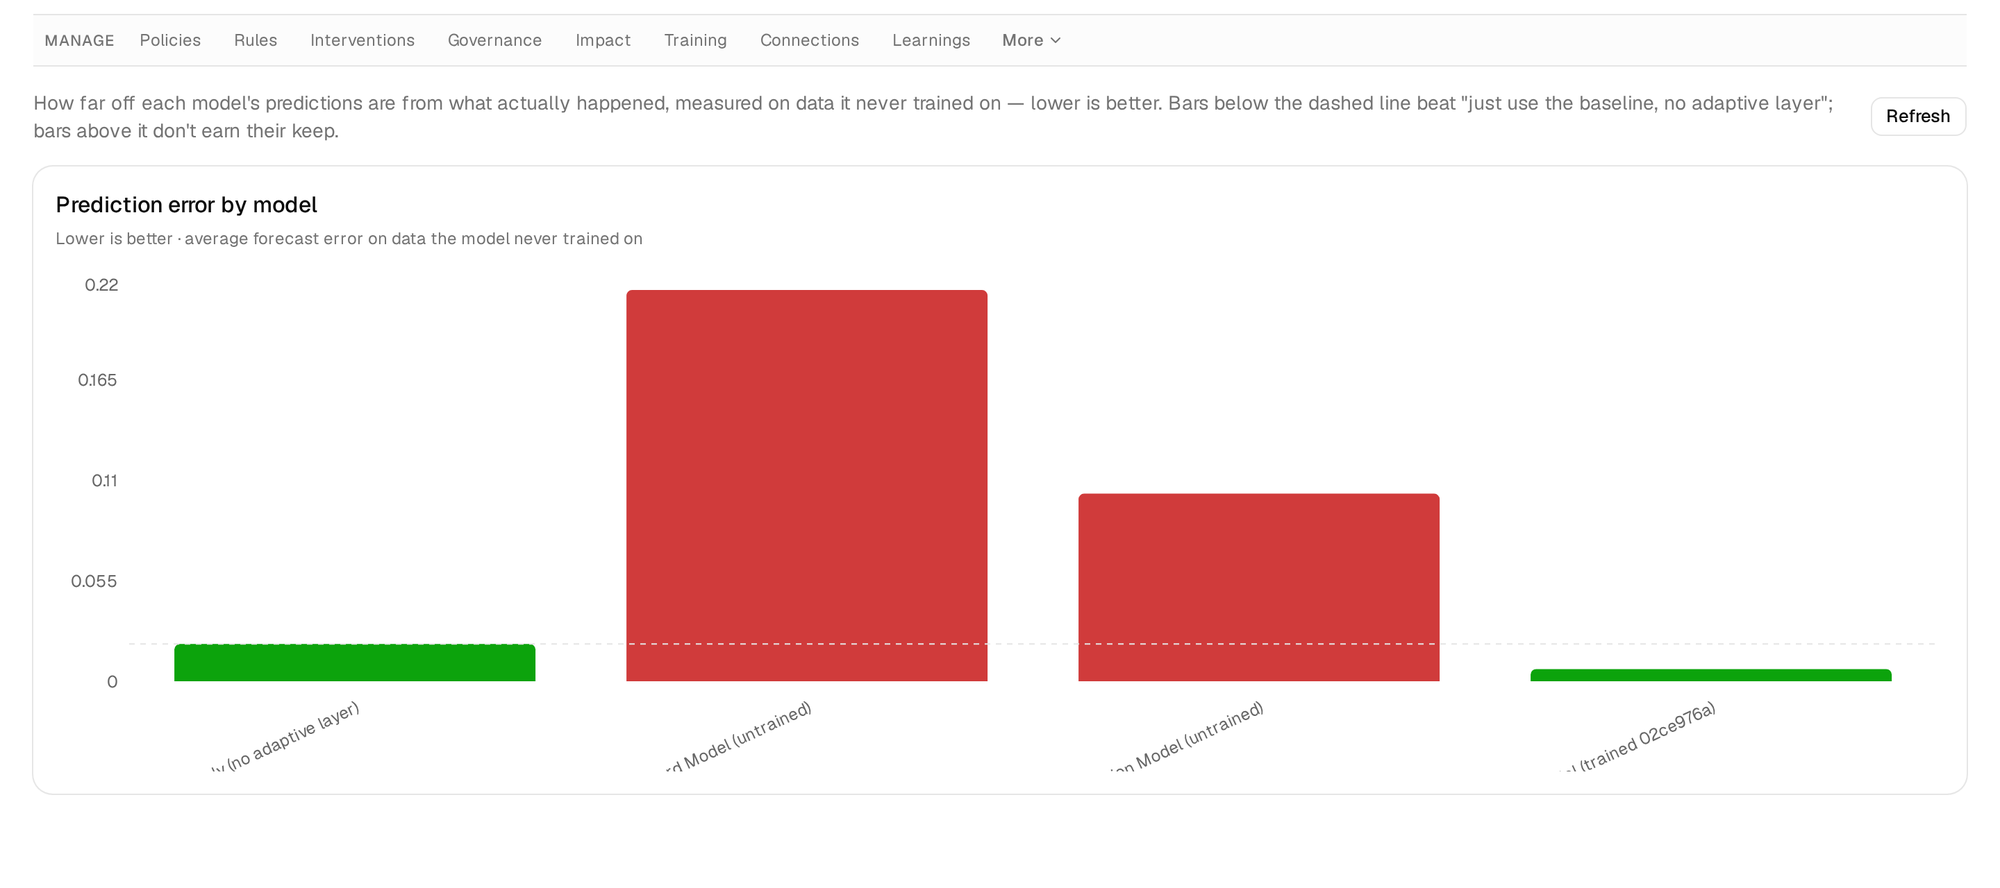
Per-horizon error against persistence, the furthest horizon at which the model still wins, the verdict, and the corpus provenance. Look for the horizons where it loses. If a vendor will not show you this, that is your answer.
Judge it, do not admire it
| Signal | What it means |
|---|---|
| The queue ordering is defensible without explanation | Ranking is doing real work |
| Conflict goes high on some cases | The evidence layer is not decorative |
| An intervention’s cost changes the recommendation | Pricing is wired into the decision, not displayed |
| The model record contains a failure | The evaluation is real |
| The what-if is instant and local | Same engine, not a demo build |
| Someone says “we would not use it that way” | They are translating it to their world, which is the best sign there is |
The five questions to ask us
Bring these. We will answer them live, on the reference world and then on your data.
- Show me the model record. Which horizons beat persistence, and which do not?
- Which horizons were not measured?
- What is the corpus provenance? How much training data is unattributed?
- Show me a refused promotion and the recorded reason.
- What is the furthest horizon you would stand behind for my domain, on my data?
Practical notes
- A session runs about 45 minutes, most of it on your domain.
- Bring a sample of real events if you can. A month is plenty, and it turns the session from a demo into an evaluation.
- Bring the person who owns the decision as well as the person who owns the data. The most revealing question is “how far ahead do you need to be right?”, and it is usually the operator who answers it.
One entity, in depth
Step two of the route: the trajectory against its events, the drivers, and the evidence panel.
A priced decision
Step three: the effect of acting against the cost of waiting.
Counterfactual replay
Step four: the same entity run forward with and without action.
The model comparison
Step six: look for the models that lose.
Book the session
Name the domain and the decision you wish you could make earlier.